Wednesday, August 22, 2012

Grimm Tales From The Doc Face

Ever since the Technical Documents page grew in size to include 1,127 links to other pages, the Google Custom Search Engine has performed very poorly.

For example, try searching for ROW_NUMBER or ASSERTION on the Technical Documents page: Google won't return nearly as many pages as exist... it won't even return some pages with those words in the title.

Sooooo... after waiting and waiting and waiting for the Google CSE to catch up, a different approach is being tried:

  • A standalone page has been created, separate from this blog, holding just the document links and nothing else,

  • a new Google Custom Search Engine has been created using one single URL (the standalone page) rather than 1,127 separate document URLs,

  • with the following Google "My search engines" settings
    Tales From The Doc Face
       Control Panel
          Sites
             Included sites
                Add sites
                   Include sites individually
                      URL: http://www.risingroad.com/Tales_From_The_Doc_Face.html
                      What to include: 
                         Dynamically extract links from this page and add them to my search engine
                            Include all pages this page links to
    
That last point is important: if "Include all pages this page links to" implies "and only those pages" then maybe the new approach will work. The last thing anyone wants is for Google to include all the other stuff those pages link to; if you want to see all of sybase.com, or the whole internet, you can use Google Classic.

Good luck, everyone!


When the new Technical Documents page starts to behave better than the old Technical Documents page, as far as searching is concerned, it will replace the old page.

Dilbert.com


Monday, August 20, 2012

Latest SQL Anywhere EBFs: 12.0.1 for SPARC and Windows

The three asterisks "***" show which Express Bug Fixes (EBFs) have been released since the previous version of this page.

  • Only EBFs for the latest fully-supported versions of SQL Anywhere are shown here: 11.0.1 and 12.0.1.

  • Just because an older version or different platform isn't "fully supported" any more doesn't mean you can't download files (or ask questions, or get help), it just means there won't be any more new EBFs released.

Current builds for the active platforms...

HP-UX Itanium   12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

IBM AIX         12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

Linux x86/x64   12.0.1.3759 EBF     23 Jul 2012
                11.0.1.2843 EBF     27 Jul 2012

Mac OS          12.0.1.3744 EBF     16 Jul 2012
                11.0.1.2449 EBF     29 Jun 2010

Solaris SPARC   12.0.1.3773 EBF *** 14 Aug 2012 ***
                11.0.1.2811 EBF     14 May 2012

Solaris x64     12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

Windows x86/x64 12.0.1.3769 EBF *** 14 Aug 2012 ***
                11.0.1.2837 EBF     31 Jul 2012

Other Stuff...

Free Technical Summit

Older EBFs

Free support! Q&A forum
...or, call Tech Support

SQL Anywhere home page 

Buy SQL Anywhere 

Download the Developer Edition... 
  [12.0.1] [11.0.1]

Download the Educational Edition 
Download the Web Edition 

Supported Platforms...
  [SQL Anywhere] [Linux] [OnDemand]

Recommended...
  ODBC Drivers for MobiLink


Friday, August 17, 2012

The fRiDaY File - The Google AutoStereotyper

"Why is X so Y?"


If you fill in a value for X, Google will solve for Y:


The official name for this feature is Google AutoComplete but with a little effort you can turn it in to "The Google AutoStereotyper": just type a partial question of the form "why is x so" and Google does the rest.

Or you can use "why are x so"...


Sometimes you can leave off the "so"...


It works with things as well as people and places...


But, not all things...


Just pick a different X...


Dilbert.com


SQL Anywhere Technical Summit Nov 14 and 15


Don't let the price tag fool you, this is The Real Thing, so please, take the survey...


Event Details

Date:
November 14th-15th, 2012

Location:
Waterloo, Ontario

Why attend the SQL Anywhere Technical Summit?

1. Education (Learn from the experts and developers themselves
2. Networking (Meet the people behind the product as well as other experienced users)
3. The training is FREE!

*The training is free however attendees are responsible for flight, hotel and other travel expenses.

 
Save the Date
SQL Anywhere Technical Summit

Hello SQL Anywhere Users,

The SQL Anywhere team is excited to announce that SAP will be hosting a ‘SQL Anywhere Technical Training’ event in Waterloo, ONT on November 14th and 15th. 

This technical training event is designed for developers who are experienced with SQL Anywhere. Ideally located in Waterloo, the main development and support location for SQL Anywhere, this will be a unique opportunity for you to meet many of the developers and support contacts that have contributed to the success of SQL Anywhere. The training event will be free* of charge, however space is limited, so discuss this opportunity with your management team now.

Mark the date on your calendar and look for our next email (early September) which will provide registration and detailed event information. In the meantime, to help ensure we have a successful event please provide your input on session topics, by completing the following survey.

Best Regards,

The SAP Sybase SQL Anywhere team


...oh, yeah, almost forgot:
The emphasis is mine.

Wednesday, August 15, 2012

Choosing Which Task To Kill

Question: How do I figure out which engine is which, in Windows Task Manager?

When I have a [cough] problem and I need to kill one of several database engines running on the same computer, it's a crap shoot trying to tell them apart... whichever one I pick always turns out to be the wrong one.

Answer: It's pretty hard to do in Windows Ancient, where "pretty hard" is code for "I don't know".

But in Windows Recent, you can tell Task Manager to show the command line that launched the engine, and in a lot of cases that's enough to tell one process from another. Just use

Task Manager 
  - Processes tab 
     - View 
        - Select Columns... 
and check "Command Line" to turn this...

into this...
You can also use
Task Manager  
  - Performance tab  
     - Resource Monitor...
        - Disk tab  
           - Disk Activity pane 
to search through the "File" values to find the server PID (process identifier) associated with a particular database file name:


Monday, August 13, 2012

Latest SQL Anywhere EBF: 11.0.1.2837 for Windows

The three asterisks "***" show which Express Bug Fixes (EBFs) have been released since the previous version of this page.

  • Only EBFs for the latest fully-supported versions of SQL Anywhere are shown here: 11.0.1 and 12.0.1.

  • Just because an older version or different platform isn't "fully supported" any more doesn't mean you can't download files (or ask questions, or get help), it just means there won't be any more new EBFs released.

Current builds for the active platforms...

HP-UX Itanium   12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

IBM AIX         12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

Linux x86/x64   12.0.1.3759 EBF     23 Jul 2012
                11.0.1.2843 EBF     27 Jul 2012

Mac OS          12.0.1.3744 EBF     16 Jul 2012
                11.0.1.2449 EBF     29 Jun 2010

Solaris SPARC   12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2811 EBF     14 May 2012

Solaris x64     12.0.1.3757 EBF     23 Jul 2012
                11.0.1.2753 EBF     13 Feb 2012

Windows x86/x64 12.0.1.3757 EBF     25 Jul 2012
                11.0.1.2837 EBF *** 31 Jul 2012 ***

Other Stuff...

Older EBFs

Free support! Q&A forum
...or, call Tech Support

SQL Anywhere home page 

Buy SQL Anywhere 

Download the Developer Edition... 
  [12.0.1] [11.0.1]

Download the Educational Edition 
Download the Web Edition 

Supported Platforms...
  [SQL Anywhere] [Linux] [OnDemand]

Recommended...
  ODBC Drivers for MobiLink

Friday, August 10, 2012

Example: String De-Duplication

Question: How do I save space by eliminating duplicate values from a string column while still being able to SELECT those values whenever necessary?

Answer: One method is to store a single copy of each different string value in a separate table, and replace the string column in the original table with a pointer to the new table.

Sounds simple, right?


Well, it's not too bad, given some of the language features built in to SQL Anywhere. Here's an example of the original table before any changes are made, plus a simple query:
CREATE TABLE t ( 
   pkey                BIGINT NOT NULL DEFAULT AUTOINCREMENT PRIMARY KEY,
   blob                LONG VARCHAR NULL );

SELECT pkey, blob
  FROM t;
The blob column can vary wildly in length, from NULL, to the empty string '', to a few characters, to megabytes in size.

Here's the new table, designed to hold t.blob values that are moved into tblob.blob:
CREATE TABLE tblob ( 
   blob_key            INTEGER NOT NULL DEFAULT AUTOINCREMENT PRIMARY KEY,
   hash_value          VARCHAR ( 64 ) NOT NULL,
   collision_counter   INTEGER NOT NULL,
   reference_count     BIGINT NOT NULL,
   blob                LONG VARCHAR NOT NULL,
   CONSTRAINT ukey UNIQUE ( hash_value, collision_counter ) );
  • The blob_key column is an artificial primary key 1, 2, 3, ... for the new table; this is where the "pointer to the new table" comes from.

  • The hash_value column is filled by applying SQL Anywhere's HASH() function to the long string in t.blob to create a much shorter but (almost?) perfect alternate version of t.blob. In other words, if two HASH() values are the same, then the two original strings are (probably) the same, and vice versa: if two HASH() values are different then the original strings are (probably) different.

  • The collision_counter column counts the number of times 0, 1, 2, ... that the same HASH() value was returned for different t.blob values. This value has remained zero during all the testing done for this article, but... who knows?

  • The reference_count column counts the number of times that separate copies of the same t.blob value were replaced by one row in tblob. This column is nice to have for testing, and it may even be needed in your application, but it does increase the overhead.

  • The blob column is where the single copy goes, and it's NOT NULL because by the time anything is stored in tblob it's known to be longer than the threshold (e.g., 100 bytes).

  • The UNIQUE constraint is a performance optimization to help with the process that inserts new rows in tblob.
Here's what the original table and query look like now, with the t.blob value moved to tblob.blob for some rows and not others:
CREATE TABLE t ( 
   pkey                BIGINT NOT NULL DEFAULT AUTOINCREMENT PRIMARY KEY,
   blob_key            INTEGER NULL REFERENCES tblob ( blob_key ), 
   blob                LONG VARCHAR NULL );

SELECT t.pkey, COALESCE ( t.blob, tblob.blob ) AS blob
  FROM t LEFT OUTER JOIN tblob 
          ON t.blob_key = tblob.blob_key;
  • The LEFT OUTER JOIN matches each row in t with the corresponding row in tblob, if one exists. If no such row in tblob exists, that means the original blob value was too short to be moved, or it was NULL in the first place.

  • The COALESCE function call returns t.blob if it isn't NULL,

  • otherwise it returns tblob.blob if there was a matching row in tblob, or

  • if neither is true, it returns NULL.
In other words, only one of t.blob_key and t.blob can be non-NULL. Both columns can be NULL, however, which is what happens when the original blob value was NULL.

Here's a sample of code that shows how to INSERT rows into t and tblob, using as test data the blob column from another table called x:
BEGIN

DECLARE @match_found                       VARCHAR ( 1 );
DECLARE @hash_value                        VARCHAR ( 64 );
DECLARE @max_existing_collision_counter    INTEGER;
DECLARE @blob_key                          INTEGER;

outer_fetch_loop: FOR f_outer AS c_outer NO SCROLL CURSOR FOR
SELECT x.blob AS @blob
  FROM x
FOR READ ONLY
DO

   IF LENGTH ( COALESCE ( @blob, '' ) ) > 100 THEN

      SET @match_found = 'N';

      SET @hash_value = HASH ( @blob, 'SHA256' );
      SET @max_existing_collision_counter = -1; 

      inner_fetch_loop: FOR f_inner AS c_inner NO SCROLL CURSOR FOR
      SELECT tblob.blob_key          AS @existing_blob_key,
             tblob.collision_counter AS @existing_collision_counter,
             tblob.blob              AS @existing_blob
        FROM tblob
       WHERE tblob.hash_value = @hash_value
       ORDER BY tblob.collision_counter
      FOR READ ONLY
      DO

         IF @blob = @existing_blob THEN
            SET @match_found = 'Y';
            SET @blob_key = @existing_blob_key;
            UPDATE tblob
               SET tblob.reference_count = tblob.reference_count + 1 
             WHERE tblob.blob_key = @existing_blob_key;
            LEAVE inner_fetch_loop;
         ELSE 
            SET @max_existing_collision_counter = @existing_collision_counter;
         END IF;
      END FOR inner_fetch_loop;

      IF @match_found = 'N' THEN
         INSERT tblob (
            hash_value,
            collision_counter,
            reference_count,
            blob )
         VALUES ( 
            @hash_value, 
            @max_existing_collision_counter + 1, 
            1, 
            @blob );
         SET @blob_key = @@IDENTITY;
      END IF;

      INSERT t ( blob_key, blob ) VALUES ( @blob_key, NULL );

   ELSE

      INSERT t ( blob_key, blob ) VALUES ( NULL, @blob );

   END IF;

   COMMIT;

END FOR outer_fetch_loop;

COMMIT;

END;
  • The IF LENGTH > 100 on line 14 checks to see if the benefits of moving t.blob into tblob is worth the overhead. If not, the INSERT down on line 61 leaves the blob in t and sets the pointer to NULL.

  • The HASH() function call on line 18 uses the SHA256 algorithm, the best that SQL Anywhere has to offer. HASH() returns VARCHAR ( 64 ) values like b9afc180bd8fa250a006229ba9c8b8eddba0b96dfcb8320740af84a4c485f5ea... in other words "trust me, it's unique".

  • The FOR statement starting on line 21 looks through all the rows in tblob with matching HASH() values. In the real world, there will (probably) be zero or one rows processed by this FOR loop, and if one row is returned the IF @blob = @existing_blob on line 31 will be TRUE.

  • The IF THEN on lines 31 through 37 handles the case where not only does the HASH() value match but so does the blob value, and it saves the tblob.blob_key value in @blob_key for later use, before using the LEAVE statement on line 37 to skip out of the inner FOR loop and resume processing at line 43.

  • The ELSE starting on line 38 handles a collision, where the HASH() value matches but not the blob value, by bumping up the value of @max_existing_collision_counter (which was initialized to -1 back on line 19).

  • The IF THEN on lines 43 through 55 handles the case where the HASH() value didn't match, so a new row in tblob must be inserted.

  • The INSERT statement on line 57 fills in the pointer (t.blob_key) while setting t.blob to NULL. This is different from the INSERT on line 61 which sets the pointer to NULL and puts the original blob value into t.blob.
Here are some numbers...
SELECT tblob.reference_count,
       LENGTH ( tblob.blob ) AS length_blob,
       length_blob * ( reference_count - 1 ) AS bytes_saved
  FROM tblob
 ORDER BY bytes_saved DESC,
       length_blob DESC;

reference_count  length_blob  bytes_saved
            101       16,080    1,608,000
          5,801          135      783,000
             87        7,447      640,442
          1,036          575      595,125
            478          962      458,874
          2,270          135      306,315
             53        4,440      230,880
            166          654      107,910
            136          591       79,785
            415          135       55,890
             78          654       50,358
            362          136       49,096
             75          608       44,992
            313          135       42,120
             71          366       25,620
             37          571       20,556
            100          162       16,038
             29          437       12,236
             23          535       11,770
             68          135        9,045
              3        4,343        8,686
             13          644        7,728
             17          366        5,856
              9          577        4,616
             15          314        4,396
              6          805        4,025
              9          474        3,792
              6          566        2,830
              5          605        2,420
              7          357        2,142
              7          355        2,130
              4          581        1,743
             10          174        1,566
              4          451        1,353
              3          584        1,168
              9          119          952
              6          183          915
              3          345          690
              3          328          656
              3          323          646
              2          639          639
              3          317          634
              4          125          375
              2          358          358
              2          303          303
              2          188          188
              2          187          187
              2          136          136
              2          107          107
              1          798            0
              1          340            0
              1          179            0
              1          141            0
              1          110            0
Some parting thoughts...
  • 100 bytes might not be a good threshold. There's a lot of overhead here, and it might not be worth it for strings that short.

  • The whole idea might not be worth it... it depends on your data, and you'll never know until you try it, but if you do go to the trouble of implementing it, don't fall in love with it until you've done some objective performance tests.

  • Unless you really need tblob.reference_count, the UPDATE on line 34 is pure waste.

  • The tblob.collision_counter column might also be a waste since it is (almost) always zero. An alternative approach might be to just skip moving the blob into tblob if a collision occurs; i.e., just leave it in t.blob, and don't bother implementing tblob.collision_counter at all.


Wednesday, August 8, 2012

Alexander's Sword: UNLOAD SELECT


Question: How do I compare the before-and-after result sets from two different versions of a SELECT statement? I want to verify that performance improvements haven't introduced any errors.

Hard Answer: Struggle with a complex query involving both result sets and a fancy FROM clause, perhaps involving a FULL OUTER JOIN, or...

Easy Answer: Dump the result sets to text files and do a file compare.

"Dump" as in UNLOAD SELECT, and "file compare" as in comp or fc or whatever utility program floats your boat:

UNLOAD [select-1] TO 'filespec-1';

UNLOAD [select-2] TO 'filespec-2';

COMP filespec-1 filespec-1

-- or --

FC filespec-1 filespec-1
UNLOAD
SELECT *
  FROM SYSTAB KEY JOIN SYSTABCOL
 ORDER BY SYSTAB.table_id, 
       SYSTABCOL.column_id
TO 'a.txt';

UNLOAD
SELECT *
  FROM SYSTAB INNER JOIN SYSTABCOL
          ON SYSTAB.table_id = SYSTABCOL.table_id
 ORDER BY SYSTAB.table_id, 
       SYSTABCOL.column_id
TO 'b.txt';

COMP a.txt b.txt

C:\projects\$SA_templates>COMP a.txt b.txt
Comparing a.txt and b.txt...
Files compare OK
Compare more files (Y/N) ?

FC a.txt b.txt

C:\projects\$SA_templates>FC a.txt b.txt
Comparing files a.txt and B.TXT
FC: no differences encountered


Monday, August 6, 2012

See [your name] In Lights!

If you have ever written an article about SQL Anywhere that's technical in nature, you should be able to find it here: Tales From The Doc Face.

569 Blog Posts
    16 Patents
   184 Techwave Presentations
   358 Other Articles

 1,127 Total

Yes, "Wow!"

1,127 is a big number, and you can Google just those articles without seeing any extra clutter...

"Patents" was the only category where every entry was included. Quite a few entries in the other categories (blogs, Techwave and "other") were excluded for "not being technical enough"... for example, not one single fRiDaY File made the cut.

If you don't see your name in this list, maybe you are part of the Borg you were published as "anon."...
Overall Rank and Article Count by Author Name
  1  289  anon.
  2  250  Breck Carter
  3  188  Glenn Paulley
  4   80  Chris Kleisath
  5   51  Eric Farrar
  6   47  Jason Hinsperger
  7   30  Tom Slee
  8   19  Joshua Savill
  9   15  Anisoara Nica
  9   15  Reg Domaratzki
 10   12  David Fishburn
 11   10  Anil Goel
 11   10  Dave Neudoerffer
 12    9  José Ramos
 13    8  Bill Hillis
 13    8  Ivan T. Bowman
 13    8  Robert Waywell
 14    7  Alex Reif
 14    7  Liam Cavanagh
 14    7  Matthew Young-Lai
 14    7  Peter Bumbulis
 15    6  Dan Farrar
 15    6  Philippe Bertrand
 16    4  Mike Paola
 16    4  Russ Chamberlain
 17    3  Brendan Lucier
 17    3  Graham Hurst
 17    3  Jim Graham
 17    3  John Smirnios
 18    2  Ali Chalhoub
 18    2  Berndt Hamboeck
 18    2  Daniel Scott Brotherston
 18    2  David Loop
 18    2  David William Hillis
 18    2  Evguenia Eflov
 18    2  Jay Hennings
 18    2  Jonathan Greisz
 18    2  Kristofer Vorwerk
 18    2  Mark Culp
 18    2  Markus Karg
 18    2  Martyn Mallick
 18    2  Mohammed Abouzour
 18    2  Paul Fast
 18    2  Rafael Kitover
 18    2  Steven McDowell
 18    2  Todd Loomis
 19    1  Anthony Scian
 19    1  Aylwin Lo
 19    1  Bill McCaslin
 19    1  Bob Holt
 19    1  Brad Coomes
 19    1  Chris Irie
 19    1  Dan Comfort
 19    1  Dan Lowe
 19    1  Darren D.V. Vaillant
 19    1  David anon.
 19    1  David Carson
 19    1  David E. DeHaan
 19    1  David Wiese
 19    1  Deanne Chance
 19    1  Douglas Navas
 19    1  Eric Giguère
 19    1  Eric Murchie-Beyma
 19    1  Gennadi Rabinovitch
 19    1  Geno Coschi
 19    1  Geoff Koch
 19    1  Hong Shi
 19    1  Ian Thain
 19    1  Jagdish Bansiya
 19    1  James Blackstock
 19    1  James Parker
 19    1  Jeff Cogswell
 19    1  Kenneth Salem
 19    1  Kurt Lichtner
 19    1  Kurt Trushenski
 19    1  Mark Wright
 19    1  Matt Carrier
 19    1  Michael Reichert
 19    1  Mumtaz Ahmad
 19    1  Paul A. Horan
 19    1  Reed Shilts
 19    1  Sam Lakkundi
 19    1  Shannon White
 19    1  Stephan Arenswald
 19    1  Stephen Beck
 19    1  Trish Genoe
 19    1  Walt Tallman

If you don't see your name OR your article, please let me know and I'll add you to the list.

Here are the rankings and article counts by category...

Blog Posts
1 239 Breck Carter
2 158 Glenn Paulley
3  69 Chris Kleisath
4  36 Eric Farrar
5  35 Jason Hinsperger
6  23 Tom Slee
7   4 Philippe Bertrand
8   2 Markus Karg
8   2 Rafael Kitover
9   1 David anon.
Patents
1 8 Anisoara Nica
2 3 Matthew Young-Lai
2 3 Peter Bumbulis
3 2 Glenn Paulley
4 1 Dan Farrar
4 1 Daniel Scott Brotherston
4 1 David William Hillis
4 1 Evguenia Eflov
4 1 Ivan T. Bowman
4 1 Kristofer Vorwerk
Techwave Presentations
 1 15 Reg Domaratzki
 2 13 Eric Farrar
 2 13 Glenn Paulley
 3 12 David Fishburn
 4 10 Dave Neudoerffer
 5  9 Chris Kleisath
 5  9 Jason Hinsperger
 6  8 José Ramos
 6  8 Robert Waywell
 7  7 Alex Reif
 7  7 Anil Goel
 7  7 Bill Hillis
 7  7 Liam Cavanagh
 8  6 Joshua Savill
 9  5 Tom Slee
10  4 Mike Paola
10  4 Russ Chamberlain
11  3 Jim Graham
12  2 Ali Chalhoub
12  2 Dan Farrar
12  2 David Loop
12  2 Jay Hennings
12  2 Jonathan Greisz
12  2 Mark Culp
12  2 Martyn Mallick
12  2 Matthew Young-Lai
12  2 Paul Fast
12  2 Steven McDowell
13  1 Anthony Scian
13  1 Bill McCaslin
13  1 Bob Holt
13  1 Brad Coomes
13  1 Breck Carter
13  1 Chris Irie
13  1 Dan Comfort
13  1 Dan Lowe
13  1 Darren D.V. Vaillant
13  1 David Carson
13  1 Deanne Chance
13  1 Douglas Navas
13  1 Eric Giguère
13  1 Eric Murchie-Beyma
13  1 Ian Thain
13  1 Jagdish Bansiya
13  1 James Blackstock
13  1 James Parker
13  1 Kurt Lichtner
13  1 Kurt Trushenski
13  1 Mark Wright
13  1 Matt Carrier
13  1 Philippe Bertrand
13  1 Sam Lakkundi
13  1 Shannon White
13  1 Stephen Beck
13  1 Todd Loomis
13  1 Trish Genoe
13  1 Walt Tallman
Other
1 289 anon.
2  15 Glenn Paulley
3  13 Joshua Savill
4  10 Breck Carter
5   7 Anisoara Nica
5   7 Ivan T. Bowman
6   4 Peter Bumbulis
7   3 Anil Goel
7   3 Brendan Lucier
7   3 Dan Farrar
7   3 Graham Hurst
7   3 Jason Hinsperger
7   3 John Smirnios
8   2 Berndt Hamboeck
8   2 Chris Kleisath
8   2 Eric Farrar
8   2 Matthew Young-Lai
8   2 Mohammed Abouzour
8   2 Tom Slee
9   1 Aylwin Lo
9   1 Bill Hillis
9   1 Daniel Scott Brotherston
9   1 David E. DeHaan
9   1 David Wiese
9   1 David William Hillis
9   1 Evguenia Eflov
9   1 Gennadi Rabinovitch
9   1 Geno Coschi
9   1 Geoff Koch
9   1 Hong Shi
9   1 Jeff Cogswell
9   1 José Ramos
9   1 Kenneth Salem
9   1 Kristofer Vorwerk
9   1 Michael Reichert
9   1 Mumtaz Ahmad
9   1 Paul A. Horan
9   1 Philippe Bertrand
9   1 Reed Shilts
9   1 Stephan Arenswald
9   1 Todd Loomis

Friday, August 3, 2012

Help! I Need An Assertion!

Not an engine assertion, not like "I've got an assertion! What should I do?", but one of my own...


Question: How do I force an exception when my SQL code hits an "impossible" situation?

In other words, how do I code an assertion test inside my stored procedure or trigger?
Answer: Pick a number, any number (as long as it's somewhere between 99000 to 99999, let's say 99002) and then use DECLARE EXCEPTION and SIGNAL:
IF [pigs were seen aloft] THEN
   BEGIN
      DECLARE @exception EXCEPTION FOR SQLSTATE '99002';
      SIGNAL @exception;
   END;
END IF;
That's all there is to it: A single chunk of code inserted into your procedure:
  • No need to DECLARE the exception somewhere else,
    that's what the local BEGIN block is for.

  • You can even use the same name "@exception" over and over again in the same procedure,
    [repeat refrain]
    that's what the local BEGIN block is for.
Here's a test:
CREATE PROCEDURE p()
BEGIN

   DECLARE @x INTEGER;

   SET @x = NULL;

   IF @x IS NULL THEN
      BEGIN
         DECLARE @exception EXCEPTION FOR SQLSTATE '99002';
         SIGNAL @exception;
      END;
   END IF;

END;
Here's what happens in dbisql:
CALL p();

Could not execute statement.
User-defined exception signaled
SQLCODE=-297, ODBC 3 State="99002"
Line 1, column 1
CALL p()
The number you pick doesn't have to be unique, that's up to you... you can use 99002 all over the place if you don't mind the aggro of not knowing where it came from.

Here's a sample that includes code for capturing and recording exceptions; in this case, the 99xxx numbers are only unique within the stored procedure because other logic takes care of identifying the procedure:
DECLARE @diagnostic_location                            VARCHAR ( 20 );
DECLARE @sqlcode                                        INTEGER;
DECLARE @sqlstate                                       VARCHAR ( 5 );
DECLARE @errormsg                                       VARCHAR ( 32767 );

...

   SELECT ...

   IF SQLCODE <> 0 THEN
      BEGIN
         DECLARE @exception EXCEPTION FOR SQLSTATE '99034';
         SIGNAL @exception;
      END;
   END IF;

   ...

   UPDATE ...

   IF @@ROWCOUNT <> 1 THEN
      BEGIN
         DECLARE @exception EXCEPTION FOR SQLSTATE '99035';
         SIGNAL @exception;
      END;
   END IF;

   ...

   INSERT ...

   IF @@ROWCOUNT <> 7 THEN
      BEGIN
         DECLARE @exception EXCEPTION FOR SQLSTATE '99036';
         SIGNAL @exception;
      END;
   END IF;

...

EXCEPTION 

   WHEN OTHERS THEN
   
      SELECT SQLCODE, SQLSTATE, ERRORMSG() 
        INTO @sqlcode, @sqlstate, @errormsg;

      IF @sqlstate LIKE '99___' THEN
         SET @errormsg = STRING ( 'Internal error ', @sqlstate );
      END IF;

      CALL rroad_exception ( STRING ( 
         @diagnostic_location, '(210eh1)', 
         ' SQLCODE = ', @sqlcode,  
         ', SQLSTATE = ', @sqlstate,  
         ', ERRORMSG() = ', @errormsg ) );

      RESIGNAL;
For more information about handling exceptions, see these earlier posts:
Tip: The All-Encompassing Try-Catch

Refactoring Foxhound: Logging Exceptions

Dump and Continue


Wednesday, August 1, 2012

Farewell and Good Luck! to Glenn Paulley

Yesterday was Glenn Paulley's last day at the company formerly known as Watcom, then Powersoft, then Sybase, then iAnywhere Solutions, then Sybase again, and now SAP.

For those of you who don't know Glenn, up until yesterday he was boss of the query engine which is that part of SQL Anywhere responsible for giving you an answer when you say SELECT.

Today, he's heading to... no, not Google, but to join the faculty of Conestoga College as Professor, Information Technology, to teach database systems, systems analysis and IS courses.

Dilbert.com

No, it's not like that at all!

In fact, this is more likely...

Dilbert.com

Yes, Glenn will be missed!

Here's the reason, in Glenn's own words:

I have been thinking of such a move for a little while. In a nutshell, I am trying to duplicate the joy I get from coaching, and earn a living at it. I have coached curling for ten years now and it is, by far, the most personally rewarding thing I have ever done. My hope is that I can convey the same passion and enthusiasm for Computer Science to Conestoga students as I can for my curling athletes, and bring to the classroom useful knowledge from my 25 years of experience that can help the students at Conestoga achieve their goals.
Those kids at Conestoga have no idea how lucky they are; their great good luck is inversely proportional to our bad luck, and a Glenn-free world is going to take some getting used to.

Maybe not ENTIRELY Glenn-free...

From time to time Glenn may grow tired of the grind, of the never ... ending ... pounding ... of ... thick ... skulls, and regale us with fresh posts on his new blog at The Ubiquitous Database.

His old blog will probably disappear, but the content will surely be preserved in perpetuity, as will all his articles here.


Monday, July 30, 2012

Latest SQL Anywhere EBFs: 8 Out Of 14... Olympic!

The three asterisks "***" show which Express Bug Fixes (EBFs) have been released since the previous version of this page.

  • Only EBFs for the latest fully-supported versions of SQL Anywhere are shown here: 11.0.1 and 12.0.1.

  • Just because an older version or different platform isn't "fully supported" any more doesn't mean you can't download files (or ask questions, or get help), it just means there won't be any more new EBFs released.

Current builds for the active platforms...

HP-UX Itanium   12.0.1.3757 EBF *** 23 Jul 2012 ***
                11.0.1.2753 EBF     13 Feb 2012

IBM AIX         12.0.1.3757 EBF *** 23 Jul 2012 ***
                11.0.1.2753 EBF     13 Feb 2012

Linux x86/x64   12.0.1.3759 EBF *** 23 Jul 2012 ***
                11.0.1.2843 EBF *** 27 Jul 2012 ***

Mac OS          12.0.1.3744 EBF     16 Jul 2012
                11.0.1.2449 EBF     29 Jun 2010

Solaris SPARC   12.0.1.3757 EBF *** 23 Jul 2012 ***
                11.0.1.2811 EBF     14 May 2012

Solaris x64     12.0.1.3757 EBF *** 23 Jul 2012 ***
                11.0.1.2753 EBF     13 Feb 2012

Windows x86/x64 12.0.1.3757 EBF *** 25 Jul 2012 ***
                11.0.1.2825 EBF *** 20 Jul 2012 ***

Other Stuff...

Older EBFs

Free support! Q&A forum
...or, call Tech Support

SQL Anywhere home page 

Buy SQL Anywhere 

Download the Developer Edition... 
  [12.0.1] [11.0.1]

Download the Educational Edition 
Download the Web Edition 

Supported Platforms...
  [SQL Anywhere] [Linux] [OnDemand]

Recommended...
  ODBC Drivers for MobiLink

Dilbert.com


Friday, July 27, 2012

Example: TOP 1, WHERE and ORDER BY

Question: How do I turn a user's guess at a value in a ordered sequence, into a value that actually exists?

For example, one of the new features in Foxhound Version 2 is the ability to "go to" a particular sample in the vast number of performance samples recorded in the database. The "go to" scroll value can be a datetime or a sample number, and it can be accurate or just a wild guess.

This question deals with a wild guess at the sample number. Here's a simplified example:

actual sample numbers in the database, in the same order that samples are displayed 
|
|    "go to" guess at the sample number
|     |
V     V

90
80
70
      65
60
50
Since sample number 65 doesn't exist, Foxhound scrolls to sample 70.

Why 70 and not 60? Because the action of "go to" is to scroll the chosen sample to the top of the display, and when the display scrolls to 70, samples 60 and 50 are visible below it. If Foxhound scrolled to sample 60 then 70 wouldn't be visible.

That's how the decision was made. There is no truth to the rumors about dice and coin tosses :)

Answer: The TOP 1, WHERE and ORDER BY clauses of the SELECT statement make this kind of query easy to code, and quite often very efficient as well.

Here's the actual code:
SELECT TOP 1 rroad_sample_set.sample_set_number
  INTO @history_goto_sample_set_number
  FROM rroad_sample_set
 WHERE rroad_sample_set.sampling_id       = @sampling_id
   AND rroad_sample_set.sample_set_number >= @candidate_history_goto_sample_set_number
 ORDER BY rroad_sample_set.sample_set_number ASC;
Here's how the TOP 1, WHERE and ORDER BY clauses work together to answer the question:
  • The WHERE ... AND predicate on line 5 limits the result set to sample numbers 70, 80 and 90... all of them are >= 65.

  • The ORDER BY ... ASC on line 6 sorts the result set so that 70 comes first.

  • The TOP 1 clause picks 70 as the final answer.

  • The input to this query is the local variable @candidate_history_goto_sample_set_number = 65, and the output is @history_goto_sample_set_number = 70.

  • The other predicate (the WHERE ... = @sampling_id on line 4) deals with the fact that Foxhound samples are partitioned by the target database being monitored.

It's perfect! What could possible go wrong?

Getting the ORDER BY wrong is a common mistake, but it's easy to fix: "ooops, that should be ASC... I think... let's try it and see."

Getting the WHERE predicate wrong is another common mistake: "should that be >= or just > ? ...or should it be < ?" ...not so easy to "just try it and see", better to think about it a bit.

In these cases "common mistake" is not an exaggeration, "almost always" is closer to the truth... if you're not an Alpha.

But, it's a valuable technique, useful in a whole variety of situations, and they all have TOP 1, WHERE and ORDER BY... you just have to pick the right WHERE operator and the right ORDER BY direction.

And if you start by scribbling down an example with data values, you can get the code right first time.

Sometimes :)


Wednesday, July 25, 2012

Webcast: SQL Anywhere On-Demand Edition (a.k.a. Fuji)

One week from today...

One hour, on Wednesday, August 1, 2012 - register here.


Monday, July 23, 2012

IS_NUMERIC()

Question: How do I check if a string is numeric?

Answer: Call ISNUMERIC().

Question: No, that checks to see if the string is a number, it accepts all sorts of crap like '-1.5E+10'. I want to check if a string is numeric... just digits.

Answer: You mean, will the string work as an UNSIGNED BIGINT?

Question: Yeah, that'll work... actually, that's exactly what I want.

Answer: Then just call CAST() and if that doesn't throw an EXCEPTION then you're good to go.

Question: I don't want to accept the empty string or all spaces or NULL.

Answer: So you want it to work just like ISNUMERIC() but without all the crap?

Question: Yeah.

Answer: OK, here you go...

CREATE FUNCTION IS_NUMERIC
   ( IN @string  LONG VARCHAR )
   RETURNS INTEGER 
BEGIN

DECLARE @unsigned_bigint  UNSIGNED BIGINT;

IF TRIM ( COALESCE ( @string, '' ) ) = '' THEN
   RETURN 0;
END IF;

SET @unsigned_bigint = CAST ( @string AS UNSIGNED BIGINT );

RETURN 1;

EXCEPTION WHEN OTHERS THEN
   RETURN 0;

END;
Here are some test cases:
SELECT CAST ( NULL AS LONG VARCHAR ) as x,  ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '' as x,     ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT ' ' as x,    ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '    9    ' as x,  ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '-1' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '-1.5E+10' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '00018446744073709551615' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '1' as x,   ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '1.0' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '1.1' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '18446744073709551615' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '18446744073709551616' as x, ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '9223372036854775807' as x,  ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT '9223372036854775808' as x,  ISNUMERIC ( x ), IS_NUMERIC ( x )
UNION
SELECT 'abc' as x,  ISNUMERIC ( x ), IS_NUMERIC ( x )
ORDER BY 1;

                         ISNUMERIC(x)
                         |   IS_NUMERIC(x)
                         |   |
x                        V   V
----------------------- --- --- 
(NULL)                   0   0
                         0   0
                         0   0
    9                    1   1
-1                       1   0
-1.5E+10                 1   0
00018446744073709551615  1   1
1                        1   1
1.0                      1   0
1.1                      1   0
18446744073709551615     1   1
18446744073709551616     1   0
9223372036854775807      1   1
9223372036854775808      1   1
abc                      0   0


Friday, July 20, 2012

The fRiDaY File - What if?

xkcd has a new feature: "What if? Answering your hypothetical questions with physics, every Tuesday."

So far three entries have been published, with the first one being the best by far:

What would happen if you tried to hit a baseball pitched at 90% the speed of light?


Latest SQL Anywhere EBF: 12.0.1.3744 for Mac OS

The three asterisks "***" show which Express Bug Fixes (EBFs) have been released since the previous version of this page.

  • Only EBFs for the latest fully-supported versions of SQL Anywhere are shown here: 11.0.1 and 12.0.1.

  • Just because an older version or different platform isn't "fully supported" any more doesn't mean you can't download files (or ask questions, or get help), it just means there won't be any more new EBFs released.

Current builds for the active platforms...

HP-UX Itanium   12.0.1.3740 EBF     15 Jun 2012
                11.0.1.2753 EBF     13 Feb 2012

IBM AIX         12.0.1.3740 EBF     15 Jun 2012
                11.0.1.2753 EBF     13 Feb 2012

Linux x86/x64   12.0.1.3750 EBF     13 Jul 2012
                11.0.1.2811 EBF     17 May 2012

Mac OS          12.0.1.3744 EBF *** 16 Jul 2012 ***
                11.0.1.2449 EBF     29 Jun 2010

Solaris SPARC   12.0.1.3740 EBF     15 Jun 2012
                11.0.1.2811 EBF     14 May 2012

Solaris x64     12.0.1.3740 EBF     15 Jun 2012
                11.0.1.2753 EBF     13 Feb 2012

Windows x86/x64 12.0.1.3750 EBF     03 Jul 2012
                11.0.1.2808 EBF     22 May 2012

Other Stuff...

Older EBFs

Free support! Q&A forum
...or, call Tech Support

SQL Anywhere home page 

Buy SQL Anywhere 

Download the Developer Edition... 
  [12.0.1] [11.0.1]

Download the Educational Edition 
Download the Web Edition 

Supported Platforms...
  [SQL Anywhere] [Linux] [OnDemand]

Recommended...
  ODBC Drivers for MobiLink

Wednesday, July 18, 2012

Product Suggestion: WITH AUTO NAME ON MISSING

Automated schema upgrades are often a requirement for embedded databases, requiring miles and miles of custom code... either that, or you don't allow any schema changes after Version 1.

Here's what makes embedded databases different from central databases:

  • Hundreds or thousands of copies of the database exist, rather than just a few (or one).

  • Embedded databases don't have database administrators... they have doctors, lawyers, truckers, accountants, salesfolk, but no DBAs.

  • Embedded databases often don't even have an IT department... not when the database is buried in a trench or hurtling down the highway.
So, when the time comes to
  • add a column,

  • or a table,

  • or an index,

  • or split a table into two,

  • or combine two tables into one,

  • or . . . re . . . design . . . every . . . single . . . thing,
what's a developer to do?

Say no?


Well, that sometimes works, and if synchronization is involved that's always the first choice.

Seriously...


Let's not talk about synchronization, just a regular embedded database: maybe one user, maybe more than one, but no MobiLink.

There are two fundamentally different approaches for an automated schema upgrade:
  1. Upgrade the old database in-place using a variety of custom ALTER statements and other code to deal with the differences, versus

  2. Deliver a new database and copy the data with custom code to deal with the differences.
Both approaches are difficult to implement and very difficult to maintain as the variety of old versions in the field multiplies and grows... with success (more sales, more databases, more upgrades, more old versions) making the situation worse.

Frankly, I don't know how Intuit does it, and I bow down before their vast superiority... I am not worthy!
It doesn't matter which approach you take, or even if you use a combination of both approaches, eventually you're going to want to use INSERT SELECT to copy data from one location to another.

...and the INSERT WITH AUTO NAME SELECT feature makes it easy(ier) to deal with schema differences between the INSERT thing and the SELECT thing.

Let's call it a "Featurette"


Not having to code long lists of column names makes INSERT SELECT easier to write and maintain: SELECT * helps, and so does INSERT ( without, the, long, list, of, column, names ).

Right now, DBAs in the audience are cringing in horror at the mere suggestion of SELECT *... that's OK, the world needs SELECT * more than it needs DBAs :)

In other words, INSERT new_table SELECT * FROM old_table is a wonderful thing.

Here'e the problem, though: if the new table has even one single additional column you can no longer use INSERT new_table SELECT * FROM old_table.
CREATE TABLE old_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT old_table VALUES ( 1, 2, 3 );
COMMIT;

CREATE TABLE new_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   x     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT new_table SELECT * FROM old_table;

Could not execute statement.
Wrong number of values for INSERT
SQLCODE=-207, ODBC 3 State="21S01"
Line 15, column 1
What you have to do, even if you're OK with the DEFAULT value being assigned to the new column, is list all the column names being copied from the old table:
INSERT new_table ( pkey, a, b ) SELECT * FROM old_table;
Sure, that's easy when there are only three columns, but when there are 50 columns increasing to 51, and it's happening with dozens of tables, and code has to deal with several different old versions each having its own set of changes, it's not just hard, it's boring, and that means it's error prone.

Let's face it: database upgrades, file conversions, whatever they've been called over the years, have never been assigned much importance by management, never been given much of the budget or much time in the schedule, or... dare it be said... never been assigned to the Alpha Engineers.

Alphas can juggle dozens of differences in their head at one time...

...the rest of us need help


The WITH AUTO NAME clause lets you code INSERT new_table SELECT * FROM old_table without the column name list:
CREATE TABLE old_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT old_table VALUES ( 1, 2, 3 );
COMMIT;

CREATE TABLE new_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   x     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT new_table WITH AUTO NAME SELECT * FROM old_table;

SELECT * FROM new_table ORDER BY pkey;

pkey,a,x,b
1,2,0,3
So far, so good, but what if you are dropping a column? The WITH AUTO NAME clause doesn't help:
CREATE TABLE old_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT old_table VALUES ( 1, 2, 3 );
COMMIT;

CREATE TABLE new_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT new_table WITH AUTO NAME SELECT * FROM old_table;

Could not execute statement.
Column 'a' not found
SQLCODE=-143, ODBC 3 State="42S22"
Line 13, column 1
OK, you could decide to never drop a column, but what if it's a big fat blob that's moving to another table (and separate code deals with that process)?

What if you really hate having unused columns hanging around? WITH AUTO NAME won't let you do a rename:
CREATE TABLE old_table (
   pkey  INTEGER NOT NULL PRIMARY KEY,
   a     INTEGER NOT NULL DEFAULT 0,
   b     INTEGER NOT NULL DEFAULT 0 );

INSERT old_table VALUES ( 1, 2, 3 );
COMMIT;

CREATE TABLE new_table (
   pkey    INTEGER NOT NULL PRIMARY KEY,
   unused  INTEGER NOT NULL DEFAULT 0,
   b       INTEGER NOT NULL DEFAULT 0 );

INSERT new_table WITH AUTO NAME SELECT * FROM old_table;

Could not execute statement.
Column 'a' not found
SQLCODE=-143, ODBC 3 State="42S22"
Line 14, column 1

Here's the Featurette Suggestion...


Allow the ON MISSING IGNORE clause on WITH AUTO NAME so that any column names in the SELECT * list that don't match column names in the INSERT table are ignored:
INSERT new_table 
   WITH AUTO NAME ON MISSING IGNORE 
   SELECT * FROM old_table;
Optional, of course, and the default would be ON MISSING ERROR just like it is now.

Give that task to one of the Alphas and it'll take less time to implement than this request took to write :)


Monday, July 16, 2012

Latest SQL Anywhere EBF: 12.0.1.3750 for Linux

The three asterisks "***" show what's new since the previous list.

  • Only EBFs for the latest fully-supported versions of SQL Anywhere are shown here: 11.0.1 and 12.0.1.

  • Note: Just because an older version or different platform isn't "fully supported" any more doesn't mean you can't download files (or ask questions, or get help), it just means there won't be any more new EBFs released. For a complete list of everything available for download see Downloads - EBFs / Maintenance.

Current builds for the active platforms...

HP-UX Itanium     12.0.1.3740 EBF       15 Jun 2012
                  11.0.1.2753 EBF       13 Feb 2012

IBM AIX           12.0.1.3740 EBF       15 Jun 2012
                  11.0.1.2753 EBF       13 Feb 2012

Linux x86/x64     12.0.1.3750 EBF ***   13 Jul 2012 ***
                  11.0.1.2811 EBF       17 May 2012

Mac OS            12.0.1.3577 EBF       24 Feb 2012
                  11.0.1.2449 EBF       29 Jun 2010

Solaris SPARC     12.0.1.3740 EBF       15 Jun 2012
                  11.0.1.2811 EBF       14 May 2012

Solaris x64       12.0.1.3740 EBF       15 Jun 2012
                  11.0.1.2753 EBF       13 Feb 2012

Windows x86/x64   12.0.1.3750 EBF       03 Jul 2012
                  11.0.1.2808 EBF       22 May 2012

To see earlier versions you'll have to go to the 
Downloads - EBFs / Maintenance page and work
your way through the menus... sorry!

Other Stuff


Friday, July 13, 2012

The fRiDaY File - "Did I remember to . . . ?"

Did I remember to turn off the stove?

. . . the iron?

. . . lock the front door?

Did I remember to...

. . . take a backup?


. . . check to see that the backups have been running?

. . . test the backup files to make sure they work?

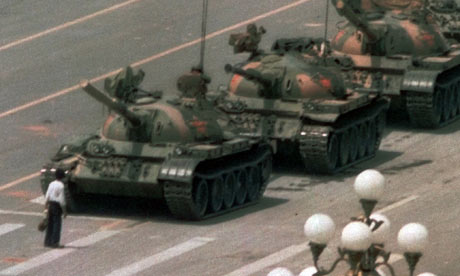
Subversive!

It's questions like those that have branded this blog as...

Enemy of the State!


What other reason could there be, to explain why this blog has been...

Blocked in China!


From now on...

I promise to be good!


Like these folks:


No more subversive questions about backups, and certainly no pictures of this guy:


Please help!

You can help re-educate this blog by not watching this video.

Please, don't watch it now!